Eleven v4
von ElevenLabs
ElevenLabs' most expressive voice model.
Audio tags, 90+ languages, and a faster Turbo tier.
Hauptfunktionen
Hören Sie die Bandbreite
Calm documentary pace, with room to breathe.
A low, gravelly read with a chuckle on cue.
Two speakers who answer each other.
One voice, speaking Japanese like a local.
Technische Spezifikationen
90+
A native accent in each, from one voice
3,000 chars
Per speech generation on Morphic
2 to 10
Speakers in one scene, 2,000 characters in total
2
Eleven v4 and Eleven v4 Turbo
Anwendungsfälle
Audiobooks and long-form
A narrator who keeps the same voice from chapter one to the last page, with the pacing to carry a slow scene.
Ads and promos
Thirty seconds that have to sell. Direct the energy with a tag and regenerate the one line that isn't landing.
Characters and games
Whispers, laughs, a sarcastic aside. The performance range for villains, sidekicks and every voice in the village.
Podcasts and audio drama
Script the whole scene with every speaker in it. The replies react to each other, so the exchange sounds like people talking.
Explainers and courses
Clear, even narration for lessons and product tours. Change one step in the script and regenerate just that line.
Localized voice-over
Run the same script in Spanish, Japanese or Portuguese and keep one voice, now with the accent each market expects.
Prompt-Beispiele
Whispered warning
[whispers] Don't turn around. [pause] He's been by the door all night.
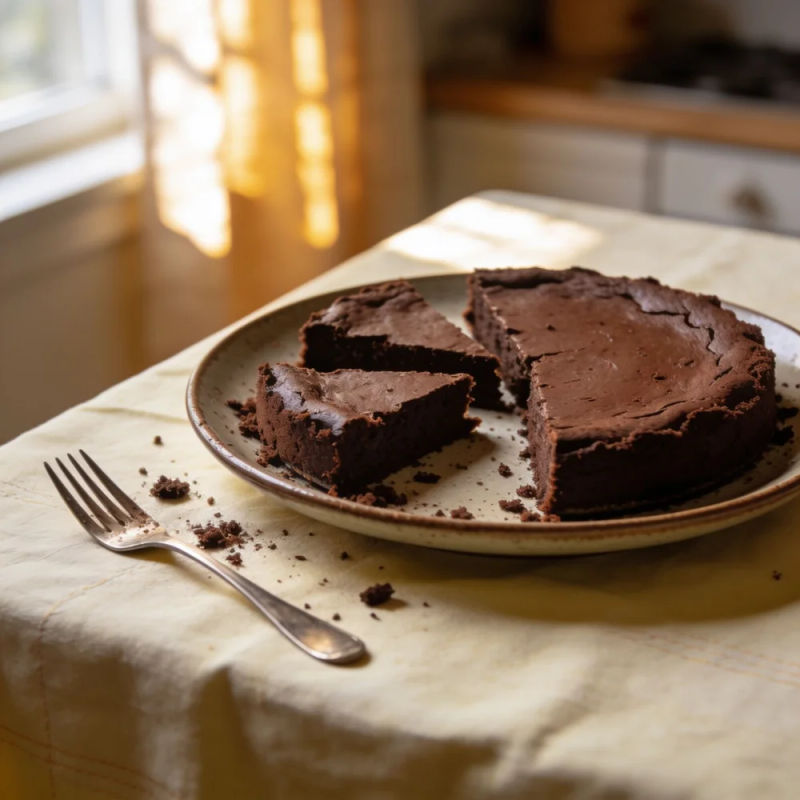
Laugh mid-line
I said the cake was sugar-free. [laughs] She'd had three slices by then.
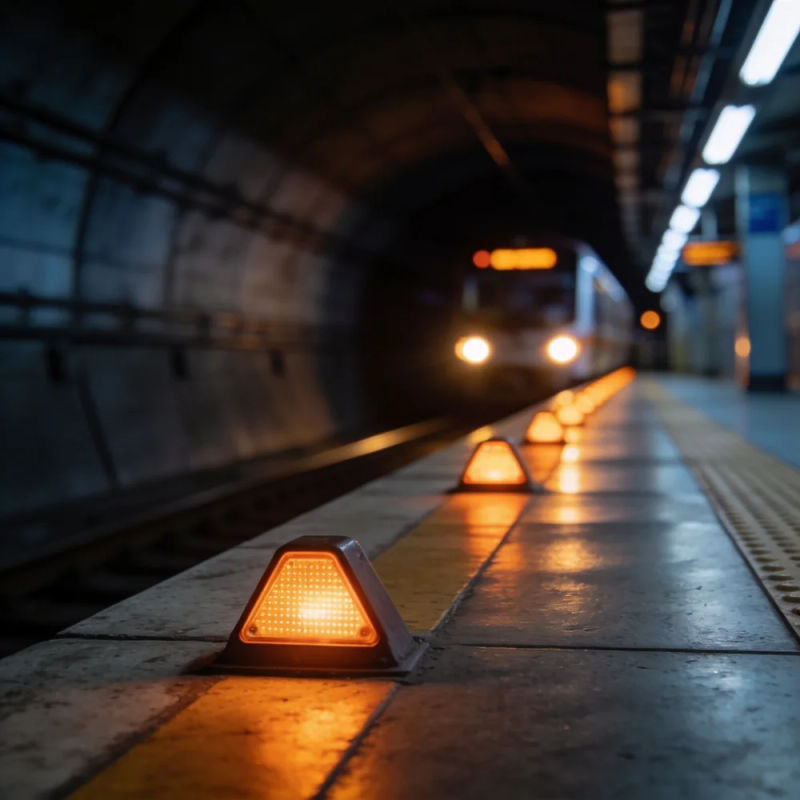
Written direction
[low, steady, urgent] Everyone off the platform. Walk, don't run.
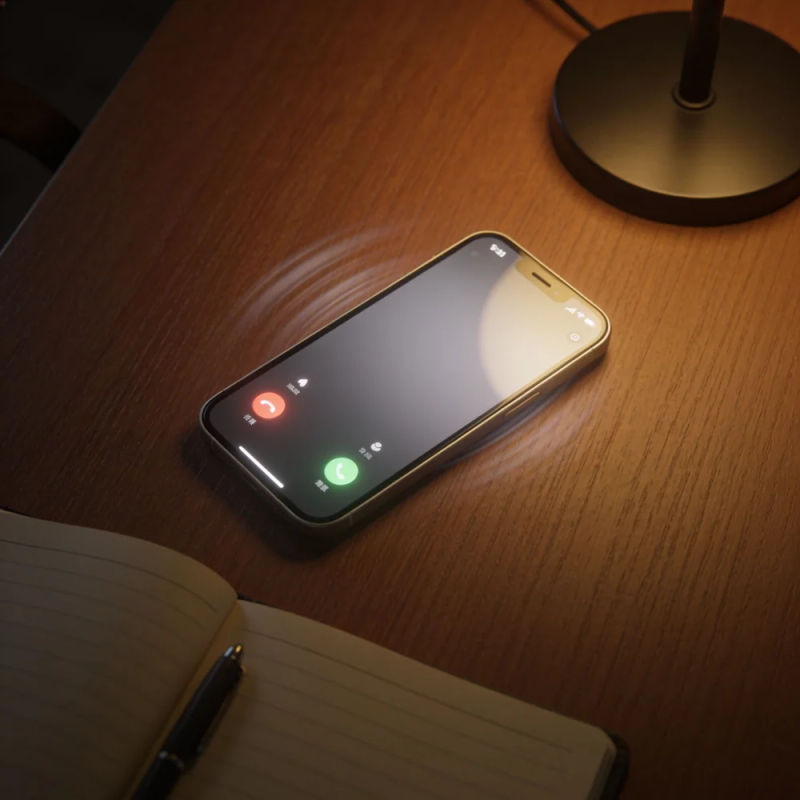
Sound in the take
[phone buzzing] That's work again. [sighs] I'll call them back later.
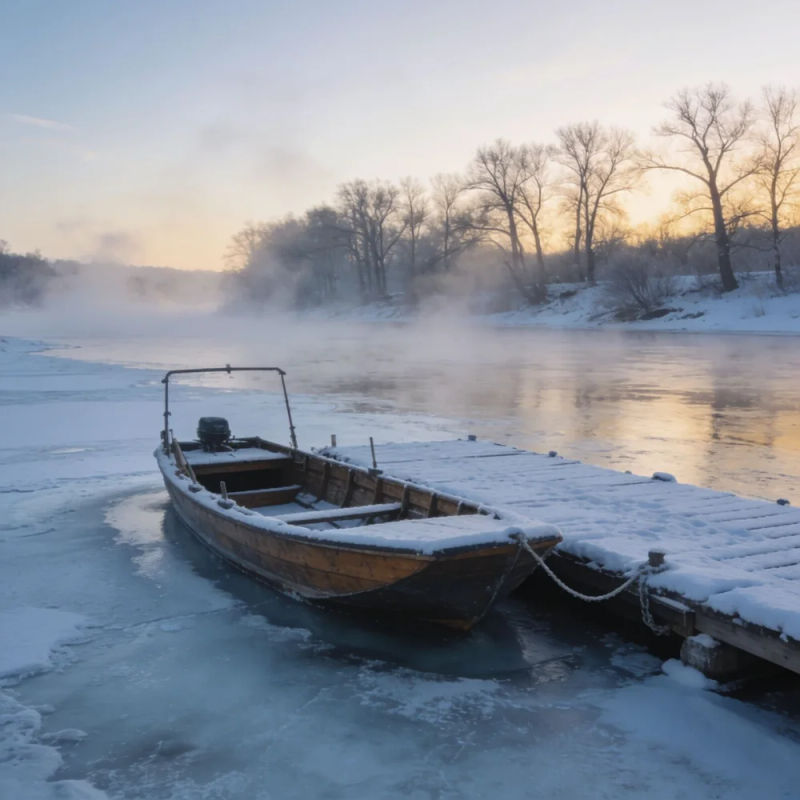
Audiobook opening
Chapter three. The river froze overnight... and the ferry never left.
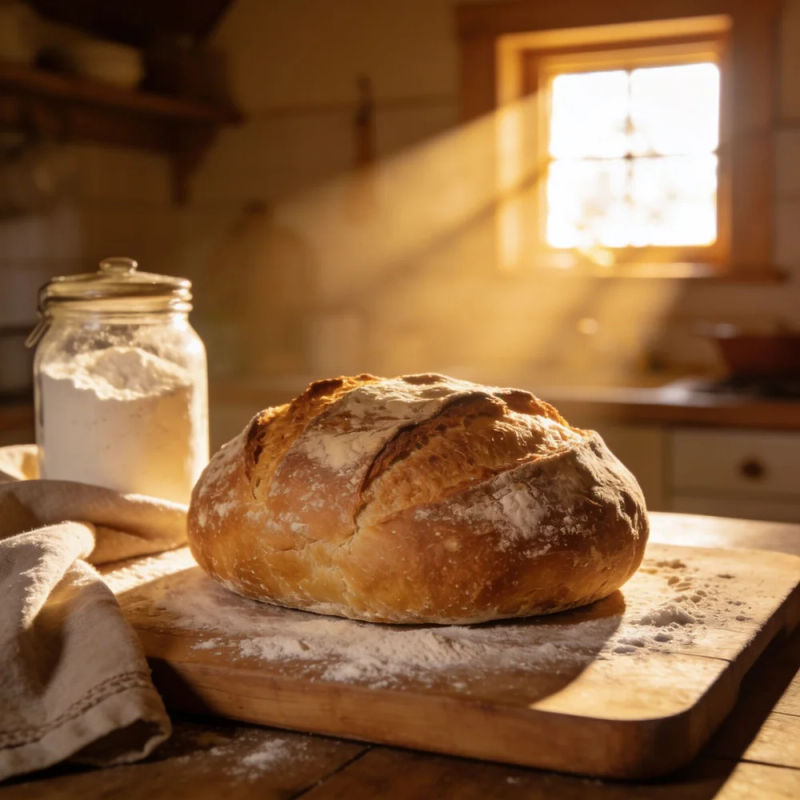
Spanish, native accent
[warm] Bienvenidos. Hoy preparamos el pan de la abuela, paso a paso.
Overview
Eleven v4 is ElevenLabs' newest text-to-speech model, released on September 28, 2026 and the default for Speech on Morphic. It reads tone and pacing from the script, takes audio tags for delivery and sound effects, runs multi-speaker dialogue, and speaks 90+ languages with a native accent.
Eleven v4 on Morphic
Open Speech and ElevenLabs is already selected on Eleven v4; choose ElevenLabs Turbo for the faster tier. Paste a script of up to 3,000 characters with audio tags inline, or switch to Dialogue for two to ten speakers. For the full tag list and how it compares with Eleven v3 and Turbo, see the Eleven v4 prompt guide.
Einfache Preise
Starten Sie noch heute kostenlos, mit der Option, jederzeit zu upgraden oder zu kündigen.
Basic
2400 monatliche Credits
1 Nutzer
Alle Modelle
Workflows
Standard
3625 monatliche Credits
1 Nutzer
Alle Modelle
Workflows
Pro
6350 gemeinsame monatliche Credits
1 Nutzer
Alle Modelle
Workflows
Max
24650 gemeinsame monatliche Credits
1 Nutzer
Alle Modelle
Workflows
Enterprise
Für höhere Limits
Individuell
Preis- und Abrechnungsbedingungen
Free
Zum Ausprobieren
$0
dauerhaft kostenlos
Häufig gestellte Fragen
ChatGPT Images 2.5
OpenAI
OpenAIs Bildmodell, erschienen im September 2026. Schärfere Details, präzise Edits, kürzere Wartezeit.
Lyria 3.5
Google DeepMind
Googles bestklingendes Musikmodell. Ganze Songs mit Aufbau und Gesang.
MiniMax H3 Max Turbo
fal.ai
Das Tempo-Modell von fal, aus H3 Max. Doppelt so schnell, fast gleiche Optik.
Inworld TTS 2
Inworld
Eine Stimme, über 100 Sprachen. 95 Stimmen, erster Ton in Echtzeit.