Dialogue scene prompt library

Copy-ready prompts for lip-synced dialogue scenes: single speaker, two-hander, argument, phone call, whisper and confession. Each explains whether to use native audio or add lip sync afterwards.

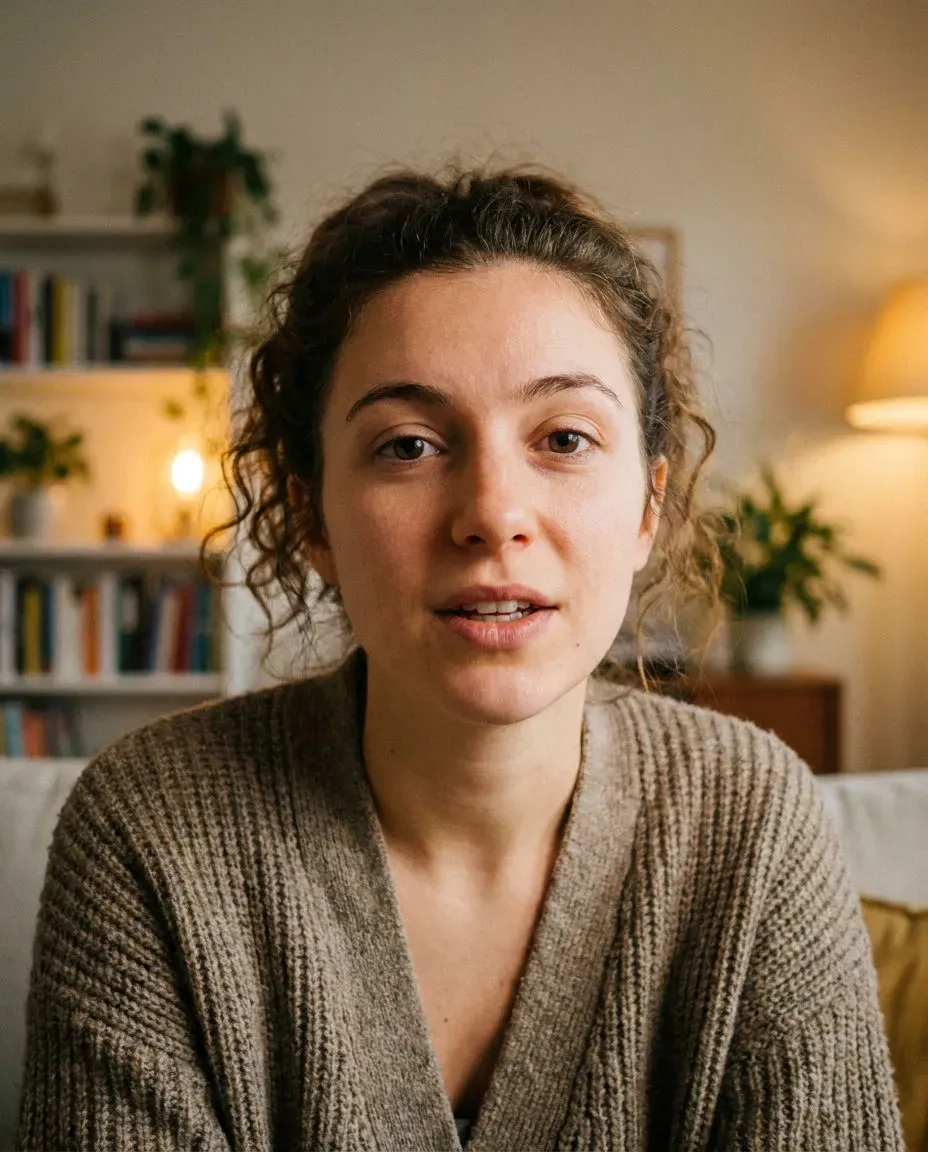
Vertical single speaker addressing the camera directly in a soft-lit room, generated with Morphic

Single speaker to camera

Vertical medium close-up of a young woman speaking directly to camera in a softly lit room, framed from the chest up with her eyes on the lens. She speaks one calm, confiding line, lips and jaw moving naturally, a small nod at the end, the head staying toward camera throughout. She says: "I wasn't going to tell anyone. But you need to hear this from me first." Soft key light from the front left, warm neutral grade, a blurred home interior behind her. The camera holds still. Natural skin, synced mouth, clear audio, cinematic, vertical 9:16, high detail, intimate and direct.

Edit prompt
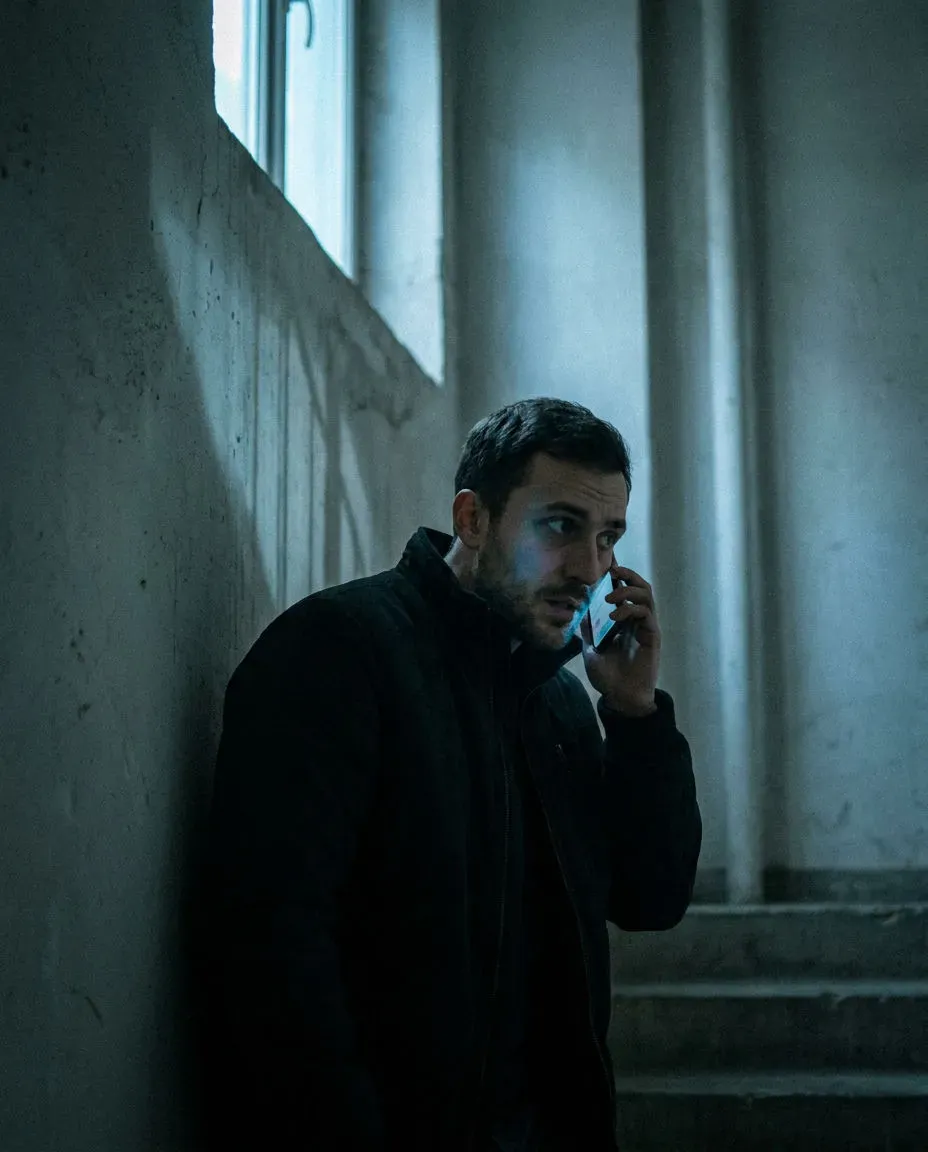
Vertical phone call with one person pressing a phone to their ear in a dim stairwell, generated with Morphic

Phone call, intercut feel

Vertical medium shot of a man pressing a phone to his ear in a dim concrete stairwell, framed from the chest up, body half-turned as if guarding the call. He listens a beat, then answers low and urgent, only his mouth moving, eyes flicking off camera. He says: "I can't talk here. Meet me where we said. Come alone." A single cold light from a window above throwing hard shadow down the wall. Faint phone glow on the side of his face. The camera holds still. Synced mouth, clear audio, cinematic cool grade, vertical 9:16, high detail, tense and hushed, built to intercut.

Edit prompt
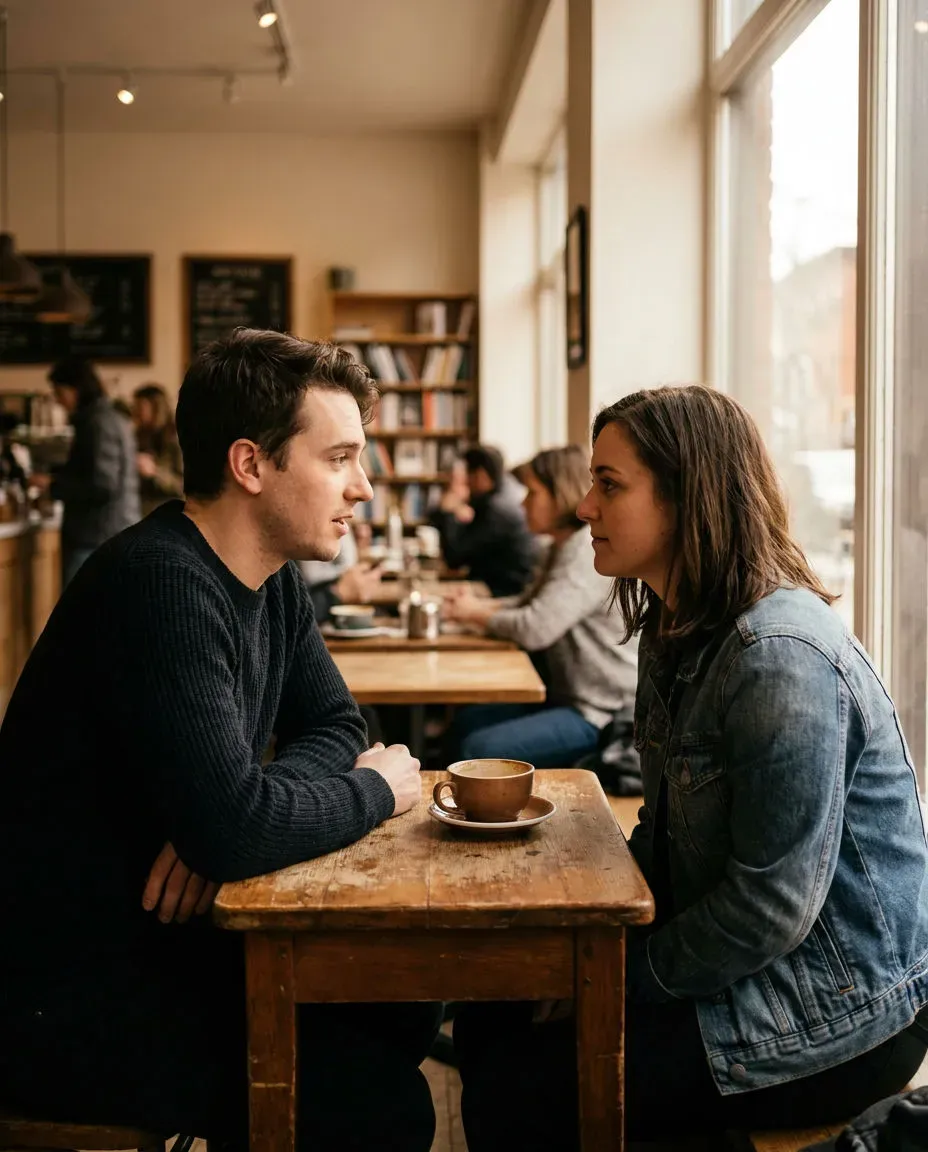
Vertical two-hander of two people talking across a small cafe table, generated with Morphic

Two-hander across a table

Vertical two-shot of two people sitting across a small cafe table in the afternoon, both faces in the frame in a loose over-the-table composition. The one on the left speaks a single measured line while the other listens, holding eye contact, a cup between them. Only the left figure's mouth moves. She says: "You already knew, didn't you? The whole time." Soft daylight through a window on the right, warm natural grade, a gently blurred cafe behind them. The camera holds still. Natural performances, synced mouth, clear audio, cinematic, vertical 9:16, high detail, quiet tension.

Edit prompt
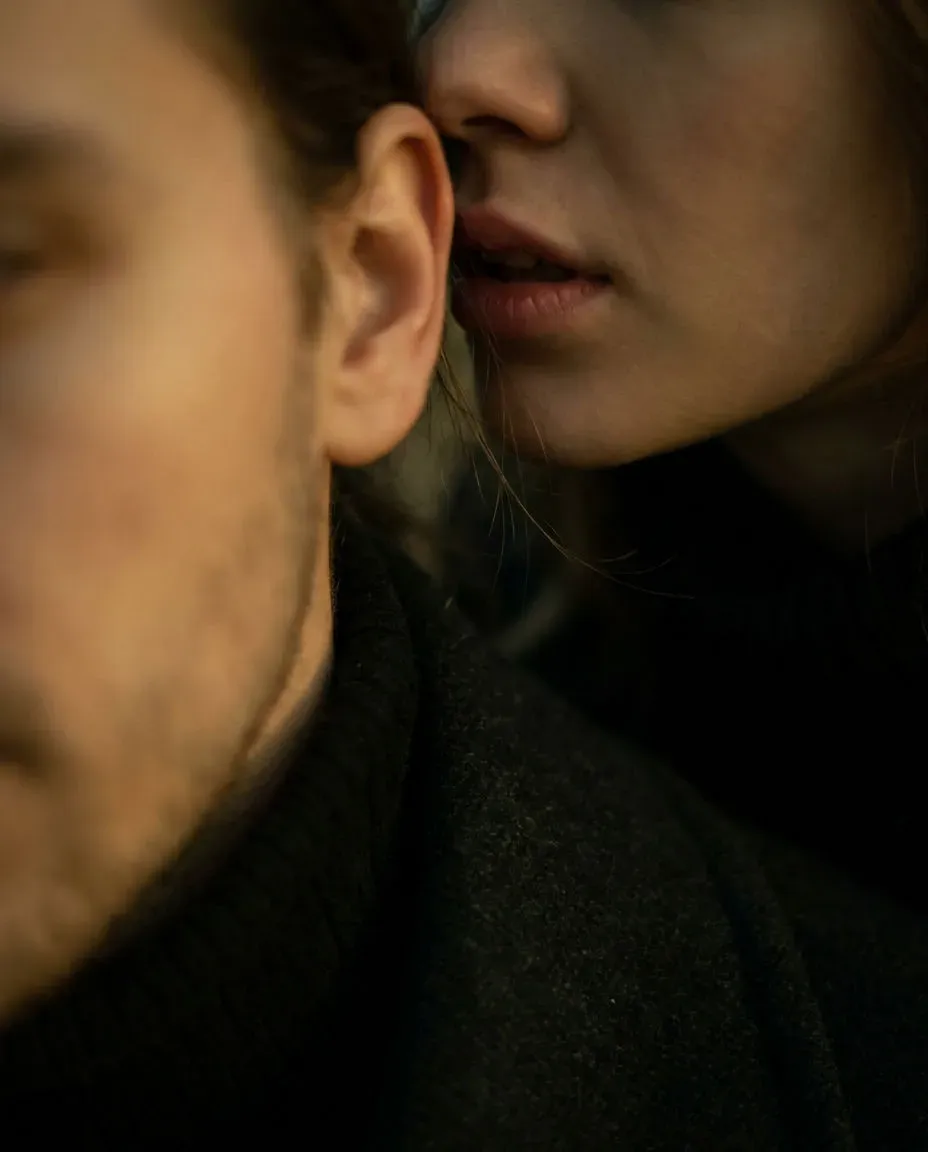
Vertical intimate whisper close-up of one person leaning in to murmur to another, generated with Morphic

Whisper, intimate close-up

Vertical extreme close-up of one person leaning in to whisper to another, framed on the two faces almost touching, the listener's ear and cheek in the foreground and the speaker's lips just behind. The speaker barely moves, a low confiding murmur, breath on the words, eyes lowered. She says, just above a breath: "Don't react. They're still watching us." Warm low light from one side, everything else soft and dark, shallow focus on the lips. The camera holds completely still. Natural skin, subtle synced mouth, cinematic, vertical 9:16, high detail, close and secret.

Edit prompt
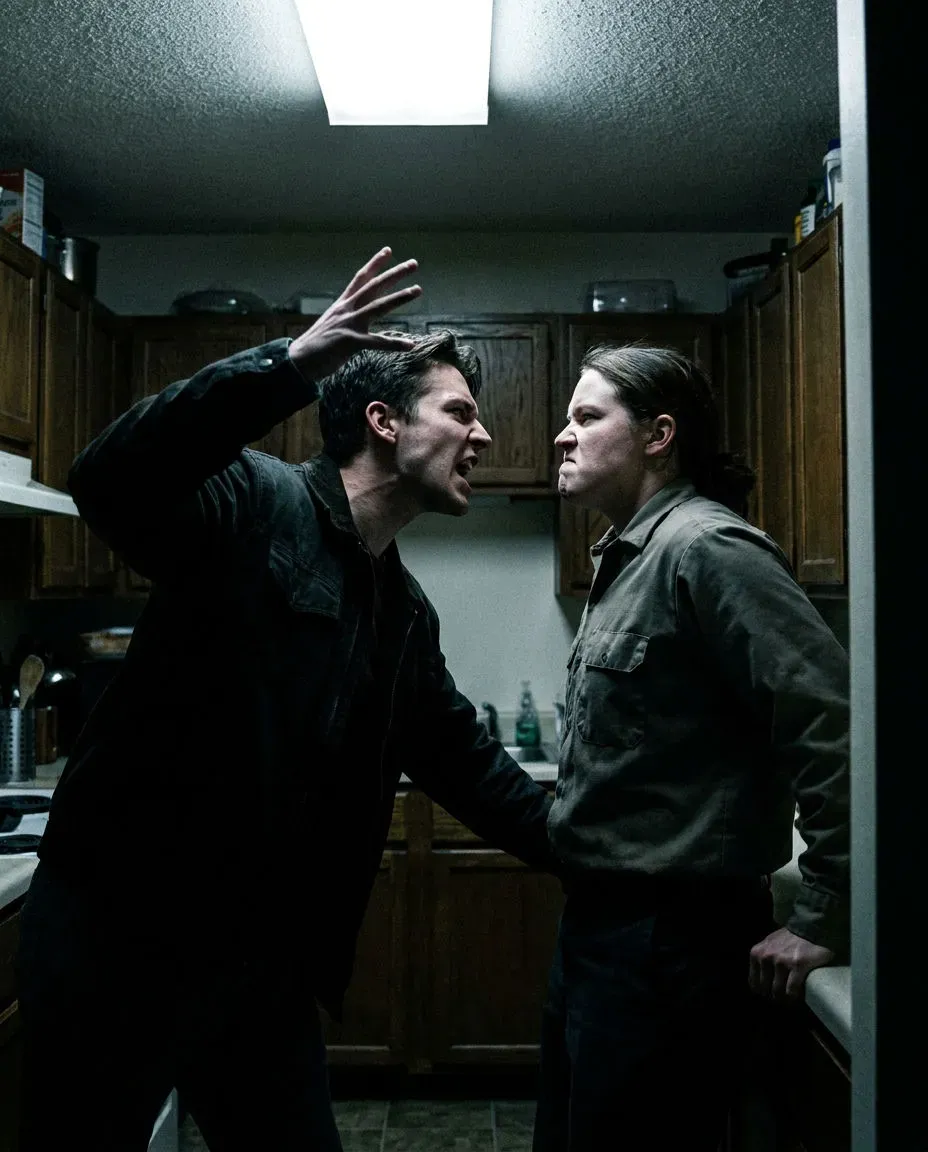
Vertical argument between two people in a kitchen at night, one raising their voice, generated with Morphic

Argument, raised voices

Vertical shot of an argument in a kitchen at night, two people a step apart, one leaning in with a raised voice and sharp gestures, the other braced and refusing to back down. Framed close so both faces read. The one leaning in delivers the line with heat, mouth moving hard, while the other's jaw tightens in response. He says: "Don't you dare walk out that door. Not after everything." Hard overhead practical light, cold grade, deep shadow at the edges. Tight handheld micro-motion. Synced mouth, clear raised audio, cinematic, vertical 9:16, high detail, volatile and physical.

Edit prompt
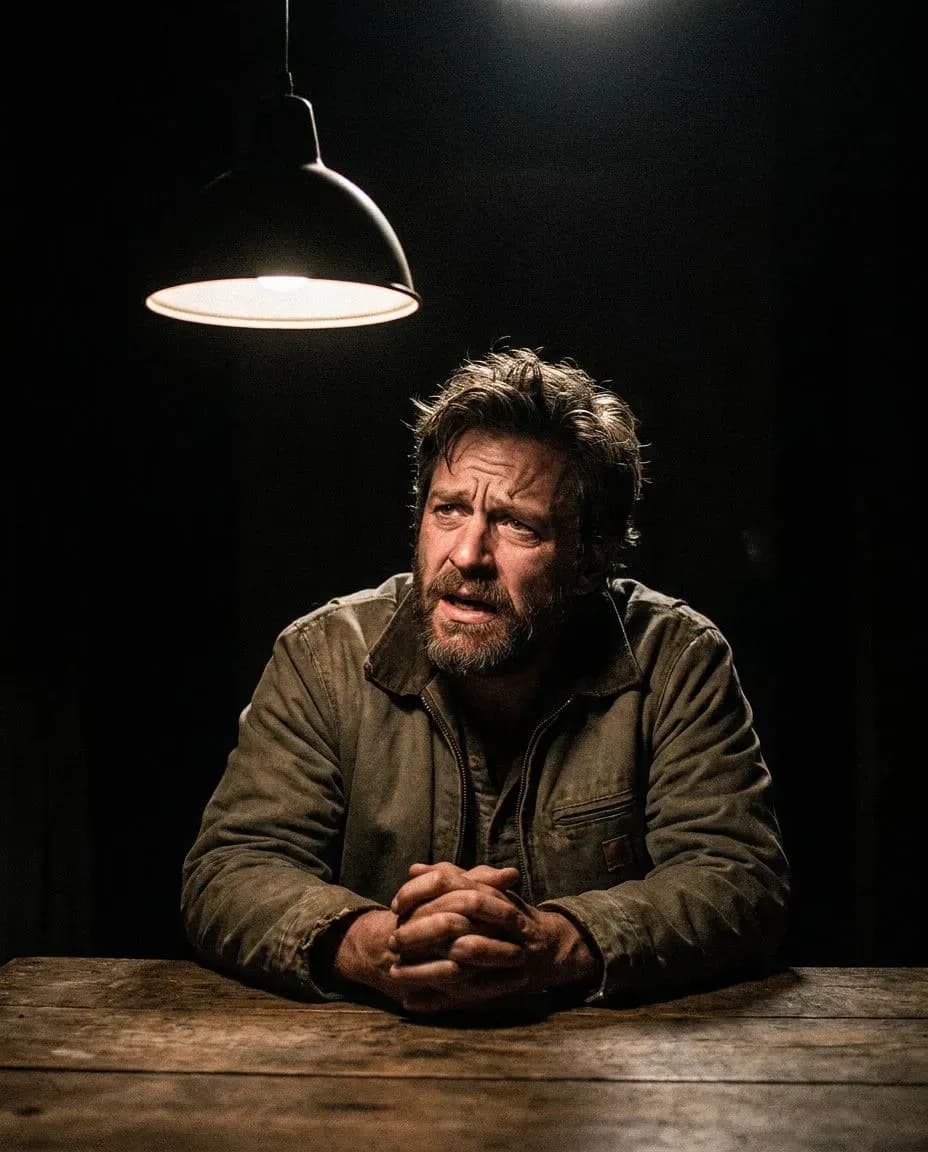
Vertical confession as a man sits alone under a single light admitting something to camera, generated with Morphic

Confession, alone under one light

Vertical medium close-up of a man sitting alone at a bare table under a single hanging light, framed from the chest up, hands clasped in front of him. He looks down, then lifts his eyes to camera and admits something in a slow, unsteady delivery with long pauses between the words. He says: "It was me. I let it happen, and I let you take the blame." One hard overhead source rimming his hair and leaving the room in near-black. The camera holds still. Natural skin, synced mouth, cinematic low-key grade, vertical 9:16, high detail, heavy and unguarded.

Edit prompt

Simple pricing

Get started for free today, with the option to upgrade or cancel anytime.

Basic

$19/ month
billed as $0 per year

2400 monthly credits

1 user only

All models

Workflows

Standard

$24/ month
billed as $0 per year

3625 monthly credits

1 user only

All models

Workflows

Pro

$45/ month
billed as $0 per year

6350 shared monthly credits

1 user

+ up to 4 more at extra cost

All models

Workflows

Max

$170/ month
billed as $0 per year

24650 shared monthly credits

1 user

+ up to 9 more at extra cost

All models

Workflows

Enterprise

For higher limits

Custom

pricing and billing terms

High-volume credits
Custom seat limits
All models
Workflows
Pricing Gradient

Free

For playing around

$0

forever free

Up to 20 credits
1 user only
Limited models
Workflows

FAQs

How do I prompt a dialogue scene?
Describe the shot the way a director would, the framing, the camera, the lighting and the performance, and give the exact line you want spoken in quotation marks so there is no ambiguity about what is said. Keep the line short, one or two sentences fits a vertical beat far better than a paragraph. Then decide between native audio and post lip sync depending on the model you are using, which each card below spells out.
Native audio or post lip sync?
A model with native audio renders the spoken line and the mouth movement together in one pass, which is the cleanest route when the line is fixed before you generate. Post lip sync is the route when you already have a silent shot you like, or a separate audio track such as a recorded voice or a dubbed language, and you want the mouth matched to it afterwards. Both live in the same workspace, so you can generate the shot and run lip sync on it without exporting anything.
How do I keep the voice consistent?
Save one voice per character and reuse it on every line that character speaks, the same way you save a face as a character reference. A saved voice holds the timbre and delivery across shots and across episodes, where re-describing it each time drifts. Pair the saved voice with the saved character reference so the sound and the face stay matched.
Why does my lip sync look off?
The usual causes are a shot where the mouth is too small in frame for the sync to read, a line that is longer than the clip, or a performance whose head turns away from camera mid-line. Frame the speaker so the mouth is clearly visible, keep the line timed to the clip length, and keep the face toward camera while the line lands. If you are syncing to a non-English track, test one short scene first before committing a whole episode, since some languages sync more cleanly than others.
Can I dub these into another language?
Yes. Dubbing in Morphic transcribes the line, translates it into one target language, re-voices it timed to the original, and returns a dubbed audio track; you then run lip sync so the mouth matches the new language. Do one target language per pass. Emotion and idiom often need a human pass to sound natural, and some Indic-language lip sync has an open issue, so test a scene first before a full season.