Seed Audio 1.5
by ByteDance
ByteDance's full‑scene audio model.
Coming soon: dialogue, music and effects as separate tracks.
Key features
Seed Audio 1.5 is coming soon to Morphic. This page covers what is known so far and updates when it opens. Use-case images are illustrations, and the samples were made with other audio models on Morphic.
Hear the range
Two voices, a corridor hum and a tense pad.
A warning, dripping water, then the gate opens.
A short jingle that ducks under the host.
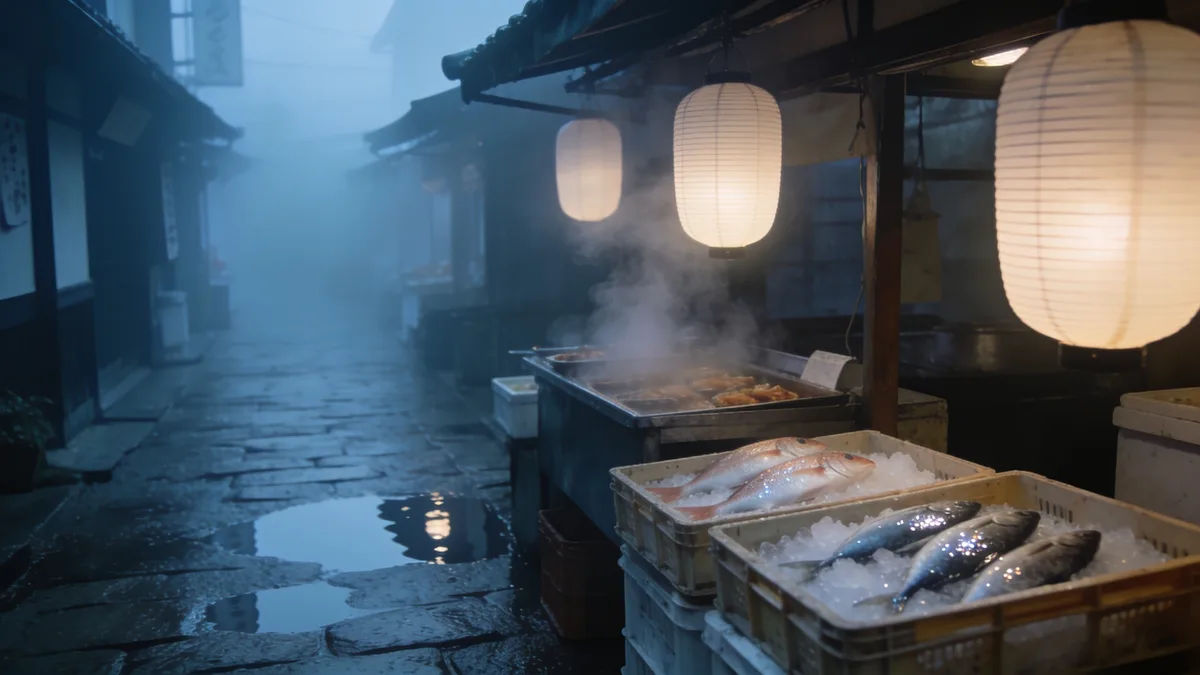
Japanese narration over a morning market.
Technical specifications
6 min
Per generation, up from 2 minutes on Seed Audio 1.0
6
Reference clips per generation, up from 3
30
Including regional variants of Spanish and Portuguese
5
Text to audio, reference voice, video to audio, video dubbing and stem separation
Use cases
Dubbing and localization
Feed in a finished cut and get a dub that follows the picture, with the original effects and music kept.
Short drama and series
Six minutes covers a full scene in one generation, and separate tracks let you revise a line without new renders.
Audiobooks and audio drama
Narration, character voices and room sound together, with the same cast held across a long chapter.
Ads and promos
Voice-over, music swell and sound effects in one pass. When the client wants changes, regenerate only that layer.
Game scenes
Character lines, environment beds and timed effects for cutscenes and trailers, cued to the second.
Podcasts
An intro jingle, two hosts and a room that sounds real, with each voice on its own track for the edit.
Prompt examples
Rainy café reunion
Rainy café, soft piano. Lena, nervous: 'You kept the ticket?' Theo laughs.
Edit promptTrailer narration
Low strings, cold wind. Deep narrator: 'Some doors should stay closed.' Thunder.
Edit promptAudiobook opening
Fire crackles, wind outside. Narrator, unhurried: 'One ship was missing.'
Edit promptOverview
Seed Audio 1.5 is ByteDance's full-scene audio model, the next version of Seed Audio 1.0, and it is coming soon to Morphic. It generates dialogue, music, ambience and sound effects from one prompt, runs up to six minutes, and takes video, voice references and timestamps as direction.
What Seed Audio 1.5 does differently
The scene comes back in layers. Dialogue, ambience, effects and music arrive as separate tracks, so a wrong line or a loud cue gets fixed on its own. Video input means the sound follows a finished cut, which is what dubbing and translation need.
Seed Audio 1.5 release date
Seed Audio 1.5 is coming soon to Morphic, and there is no date yet. Early access is paused on the provider's side while the model is updated, so it is not in Morphic's model list for now. Its features are known, listed above; when it opens and at what price come with the launch.
Seed Audio 1.5 alternatives you can use today
- Seed Audio 1.0: dialogue, music and sound effects together from one prompt, on every plan including Free.
- ElevenLabs v4: expressive speech and multi-voice dialogue.
- Lyria: music beds and stings.
- Mirelo SFX 2.0: scores a finished video with effects and ambience and keeps its dialogue, on paid plans.
They share one Canvas, so you can build the scene in layers today. For prompt structure, see the Seed Audio 1.5 prompt guide.
Simple pricing
Get started for free today, with the option to upgrade or cancel anytime.
Basic
2400 monthly credits
1 user only
All models
Workflows
Standard
3625 monthly credits
1 user only
All models
Workflows
Pro
6350 shared monthly credits
1 user
All models
Workflows
Max
24650 shared monthly credits
1 user
All models
Workflows
Enterprise
For higher limits
Custom
pricing and billing terms

Free
For playing around
$0
forever free
FAQs
LTX 2.5 Reframe, Upscale and HDR
Lightricks
Lightricks' finishing tools for any clip. New shapes, more pixels and HDR, with no prompt.
Seedance 2.5 Flash
ByteDance
ByteDance's faster, lower-cost edition of Seedance 2.5. Quicker drafts and more takes at 480p and 720p.
Seedream 5.5
ByteDance
ByteDance's Seedream image model, released November 2026. Clean multi-round edits, lifelike realism, and sharper text.
Gemini Omni Flash 1.2
Google DeepMind
Google's video model, now fifteen seconds long. Edit the whole take for 30% less a second.