OmniHuman 2.0
by ByteDance
ByteDance's audio‑driven human video model.
One photo, one track, five minutes in one take.
Key features
Specs are BytePlus's own, from its October 15, 2026 launch post. OmniHuman 2.0 is not on Morphic yet, so the clips on this page were made on Morphic with Veed Fabric, which turns one photo and one audio track into a talking video up to 5 minutes long today.
Technical specifications
5 min
One continuous shot, per BytePlus
60 s
The single-shot cap before 2.0
Photo + audio
One image of the performer and one track
Any track
Speech, music or dialogue
Use cases
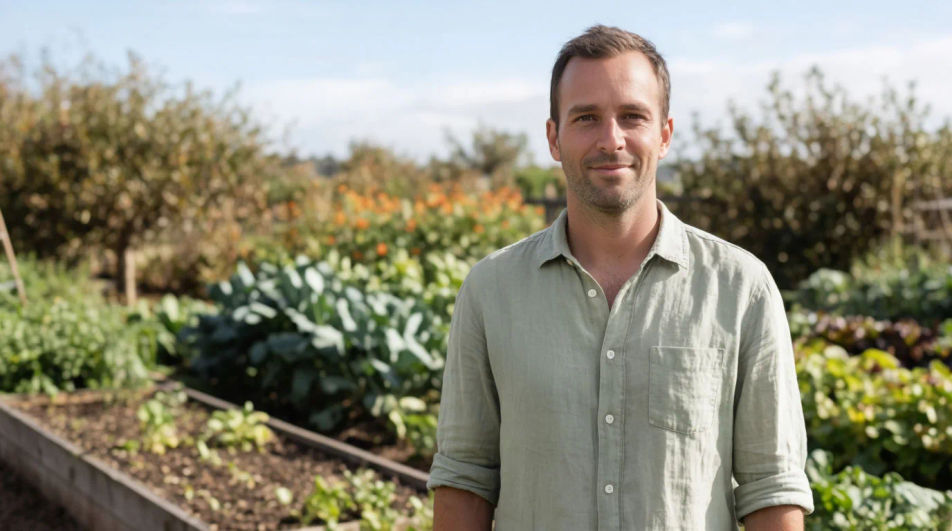
Courses and lessons
A full lesson in one take, so the instructor looks the same in minute four as in minute one and nothing needs cutting together.
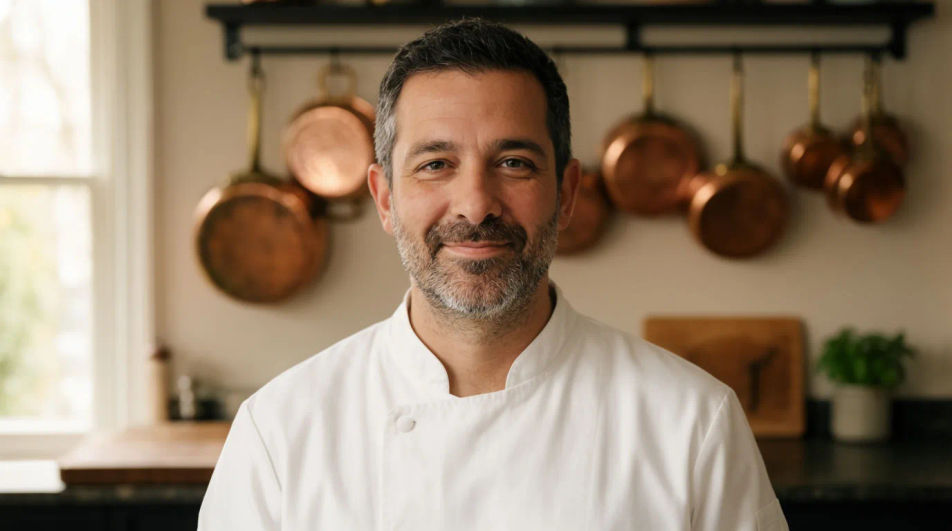
Explainers and how-to videos
Record or generate the voiceover first, then let one photo deliver it, with the pauses and emphasis that keep a viewer watching.
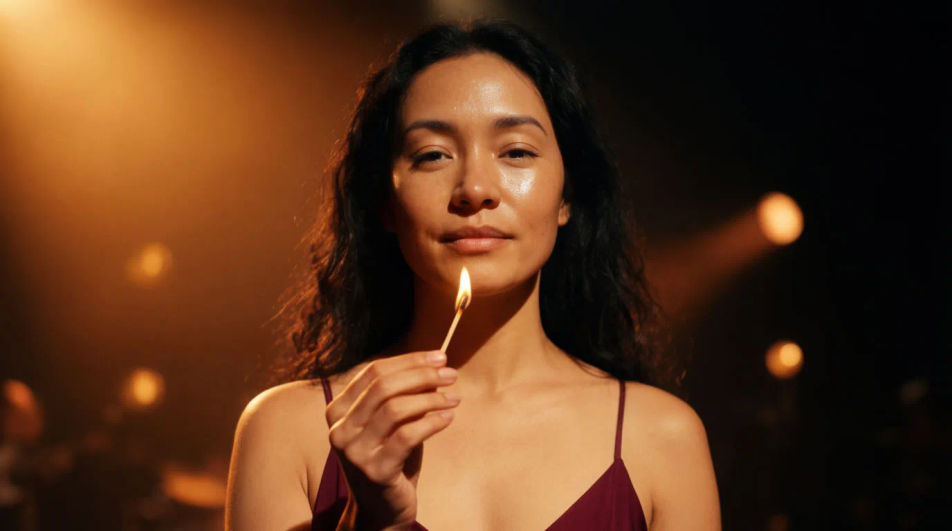
Music performance clips
Give it a sung track and the face carries the long notes, the breaths and the feeling of the song, not just the words.
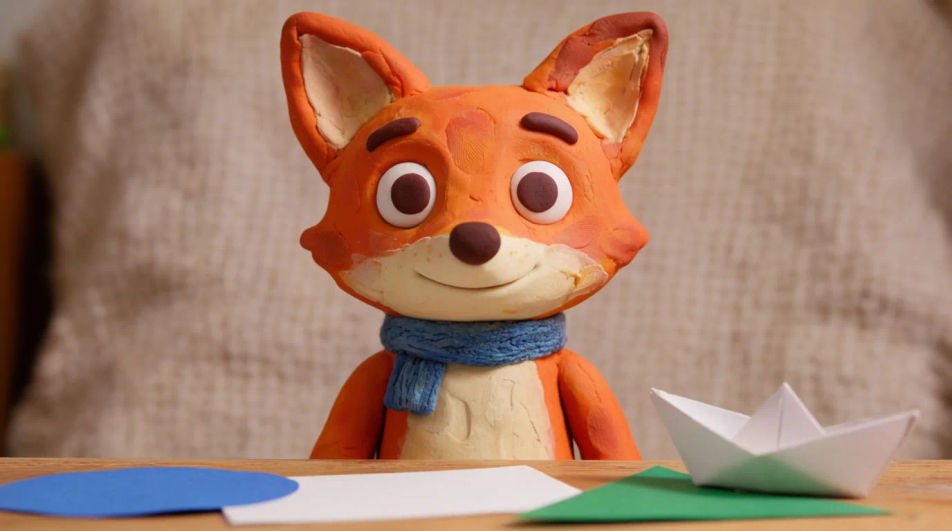
Mascots and characters
Give a brand mascot, a clay character or an illustrated hero a voice for ads, kids' content and channel intros.
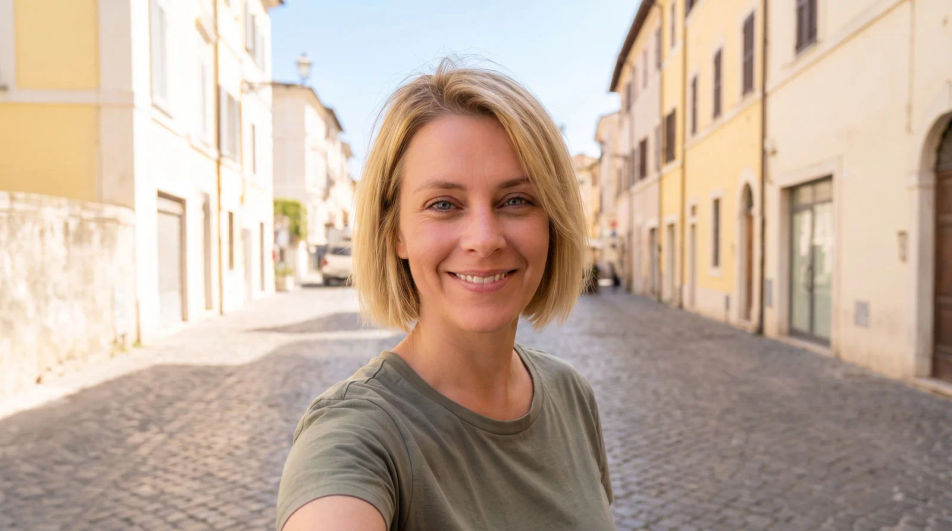
Creator and social videos
Vertical talking clips for reels and shorts from a single selfie-style photo and a voice track, ready to post.
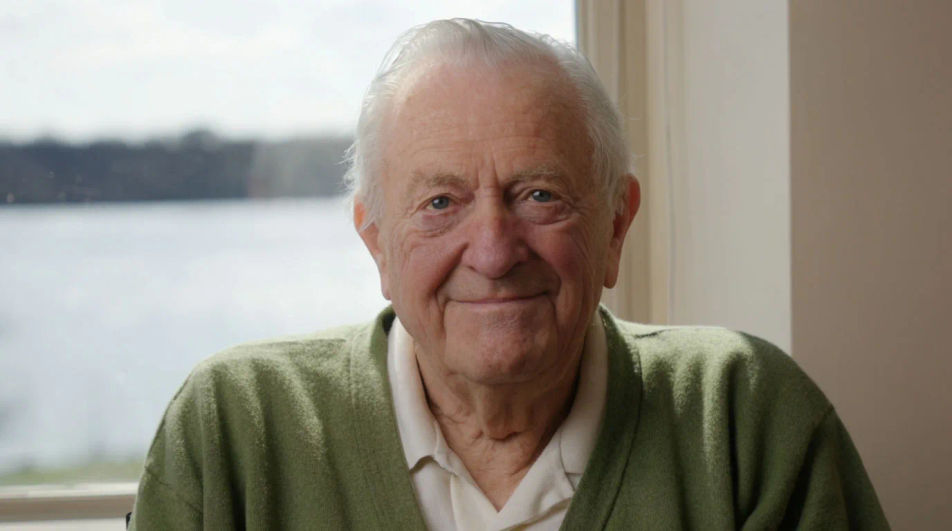
Stories and podcasts
Long spoken stories keep their rhythm, from the quiet build to the punchline, without the performer resetting every minute.
Overview
OmniHuman 2.0 is ByteDance's audio-driven human video model, released through BytePlus on October 15, 2026. It turns one photo and one audio track into a video of that person performing the track, and it reads the tone, the emotion and the words in the audio rather than only matching mouth shapes. A single shot can now run up to 5 minutes, up from 60 seconds, with no stitching (source).
What OmniHuman 2.0 does differently
Most talking-photo models move the mouth to the sound. OmniHuman 2.0 listens for how a line is said, so a whispered bedtime story, a shouted cue from a coach and a held note in a song each come out as different performances from the same kind of input. The longer single take matters as much: a lesson, a story or a full song runs as one shot, so there is no join where the face, the light or the background can change.
OmniHuman 2.0 on Morphic
OmniHuman 2.0 is coming to Morphic soon. Until then, Veed Fabric does the same job: open Copilot, attach a photo and an audio track, and ask for a talking video. Every clip on this page was made that way. For how to get the best result, see the OmniHuman 2.0 guide.
Simple pricing
Get started for free today, with the option to upgrade or cancel anytime.
Basic
2400 monthly credits
1 user only
All models
Workflows
Standard
3625 monthly credits
1 user only
All models
Workflows
Pro
6350 shared monthly credits
1 user
All models
Workflows
Max
24650 shared monthly credits
1 user
All models
Workflows
Enterprise
For higher limits
Custom
pricing and billing terms
Free
For playing around
$0
forever free
FAQs
More about OmniHuman 2.0
Guides, prompts, and comparisons for OmniHuman 2.0.
Other models
Explore the rest of the Morphic model catalog.
Mirelo SFX 2.0
Mirelo AI
Mirelo's video-to-sound model. New sound for your video, same dialogue.
Fish Audio Drama 3
Fish Audio
Fish Audio's most expressive voice model. Direct the performance, down to the word.
Vidu Q4
Shengshu Technology
Shengshu's latest video model. Up to 12 reference images and 3 voices held consistent across one clip, with native audio from 540p to 4K.
Nano Banana 2.1
Google DeepMind
Google DeepMind's new Flash image model. Better design, cleaner edits, steadier characters.